From Risk Scores to Action
Building a retention watchlist that staff can actually use
Retention models often produce more names than a student-success team can reasonably review. At that point, a technically strong model can still fail as a decision tool: the list is too long, the signals arrive too late, or staff cannot tell which changes deserve attention.
If an institution can provide meaningful follow-up to only a portion of the students flagged, that capacity must help determine the model's operating point. In a retention process I developed in higher education, I combined cohort-specific prediction, within-cohort ranking, weekly behavioral signals, professional judgment, and post-outcome validation. The model does not replace advising or student-success expertise. It focuses limited attention where a closer look may be useful.
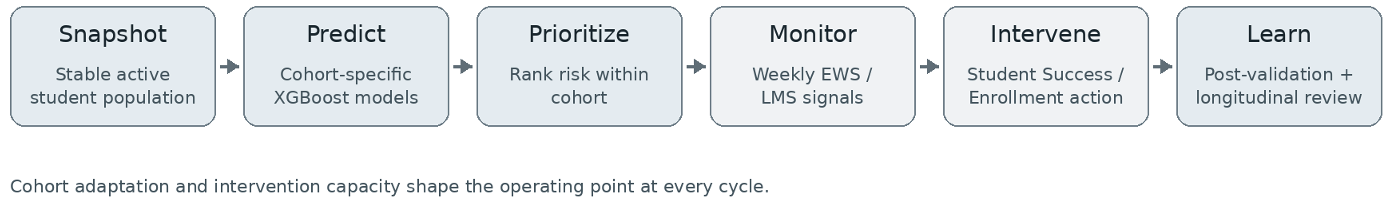
Figure 1. A recurring workflow connects prediction to staff capacity, current information, and later outcomes.
Start with a Stable Population and a Clear Outcome
Each cycle begins after enrollment has stabilized for the term. In the implementation that motivated this framework, the active population was established after the final drop deadline. Historical enrollment rosters and leave or absence records were then used to define whether students returned for the next relevant period. Roughly 10 years of history were available, with another set of observed outcomes added after each cycle.
The exact snapshot date and outcome definition will vary by institution, but they must be documented before modeling begins. Otherwise, small changes in who is included or what counts as departure can make results difficult to compare over time.
Allow for Differences Across Stages of Enrollment
I fit separate models for students at different stages of academic progression. First-year students and continuing students contribute different amounts and types of institutional information, and their departure patterns may differ. The implementation uses XGBoost, but the algorithm is less important than testing whether the segmentation improves useful, out-of-sample performance. A pooled model may be more stable at institutions with smaller cohorts, so separate models should be treated as a design choice to validate, not a universal rule.
Rank within Cohort, then Let Capacity Set the List Size
The models produce probabilities, but the operational workflow relies mainly on each student's rank within the relevant cohort. Probability distributions can differ across cohort-specific models: the highest-risk 15% in one cohort may begin near 0.70, while the same share in another cohort begins much lower. A single probability cutoff can therefore create very uneven lists.
We examined watchlists covering about 5%, 10%, 15%, 20%, and 25% of each cohort. Larger lists captured more eventual departures but also created more cases for staff to review. After discussion with Student Success and Enrollment staff, roughly 15% became the practical operating point because it matched a workload they believed they could sustain. That percentage is not a benchmark for other institutions. The transferable step is to translate available staff time into an approximate number of cases, then choose a list size that respects that limit.
Use Current Signals to Support Timing and Context
A semester-level score becomes less useful as the term unfolds unless staff can see what has changed. A BI monitoring layer can add weekly warning activity, LMS engagement, current registration, assessment information, and other timely indicators. In this implementation, warnings refreshed weekly, and the model, watchlist, and dashboard were prepared within about two to three weeks of the stable snapshot.
The distinction matters: the model identifies students who may warrant attention, while refreshed information helps staff decide whether follow-up is timely and appropriate. Student-facing professionals retain responsibility for interpreting individual circumstances and choosing any outreach.
Evaluate the Decision Process, Not Only the Model
I review held-out area under the curve (AUC), the confusion matrix, precision, and recall, but I also use a capacity-oriented measure that operational teams can interpret: among students who eventually left, what proportion appeared on at least one earlier watchlist? Across retrospective checks, this combined-list capture rate has generally been about 60% to 80%, depending on cohort and period.
That figure should always be reported with the watchlist size, time period, and denominator because capture naturally increases as a list grows. Reviews should also examine false negatives, changes in performance over time, and whether particular student groups are flagged disproportionately.
What Can Transfer to Another Institution?
- Define a stable population snapshot and a reproducible retention outcome.
- Test whether cohort-specific models add value over a pooled model.
- Convert staff capacity into an explicit watchlist size rather than choosing a threshold in isolation.
- Separate periodic prediction from more frequently refreshed monitoring signals.
- Compare earlier lists with later outcomes and audit performance, drift, and subgroup impacts.
Retention analytics becomes operationally useful only when prediction, capacity, timing, and professional judgment are designed together. A watchlist is not the intervention and it is not a verdict about a student. It is a structured way to decide where limited attention may be most valuable, learn from later outcomes, and improve the process in the next cycle.
 Yifan Liu is a Data Analyst at Rensselaer Polytechnic Institute (RPI), where he applies data science and machine learning to student retention, enrollment, admissions, and early-warning analytics. His work focuses on predictive modeling and scalable decision-support workflows that translate complex data into timely guidance, with broader interests in responsible AI for institutional decision-making.